Client Express
A bilingual SaaS that turns a business's documents into an embeddable AI support chatbot that answers only from that content.
About This Project
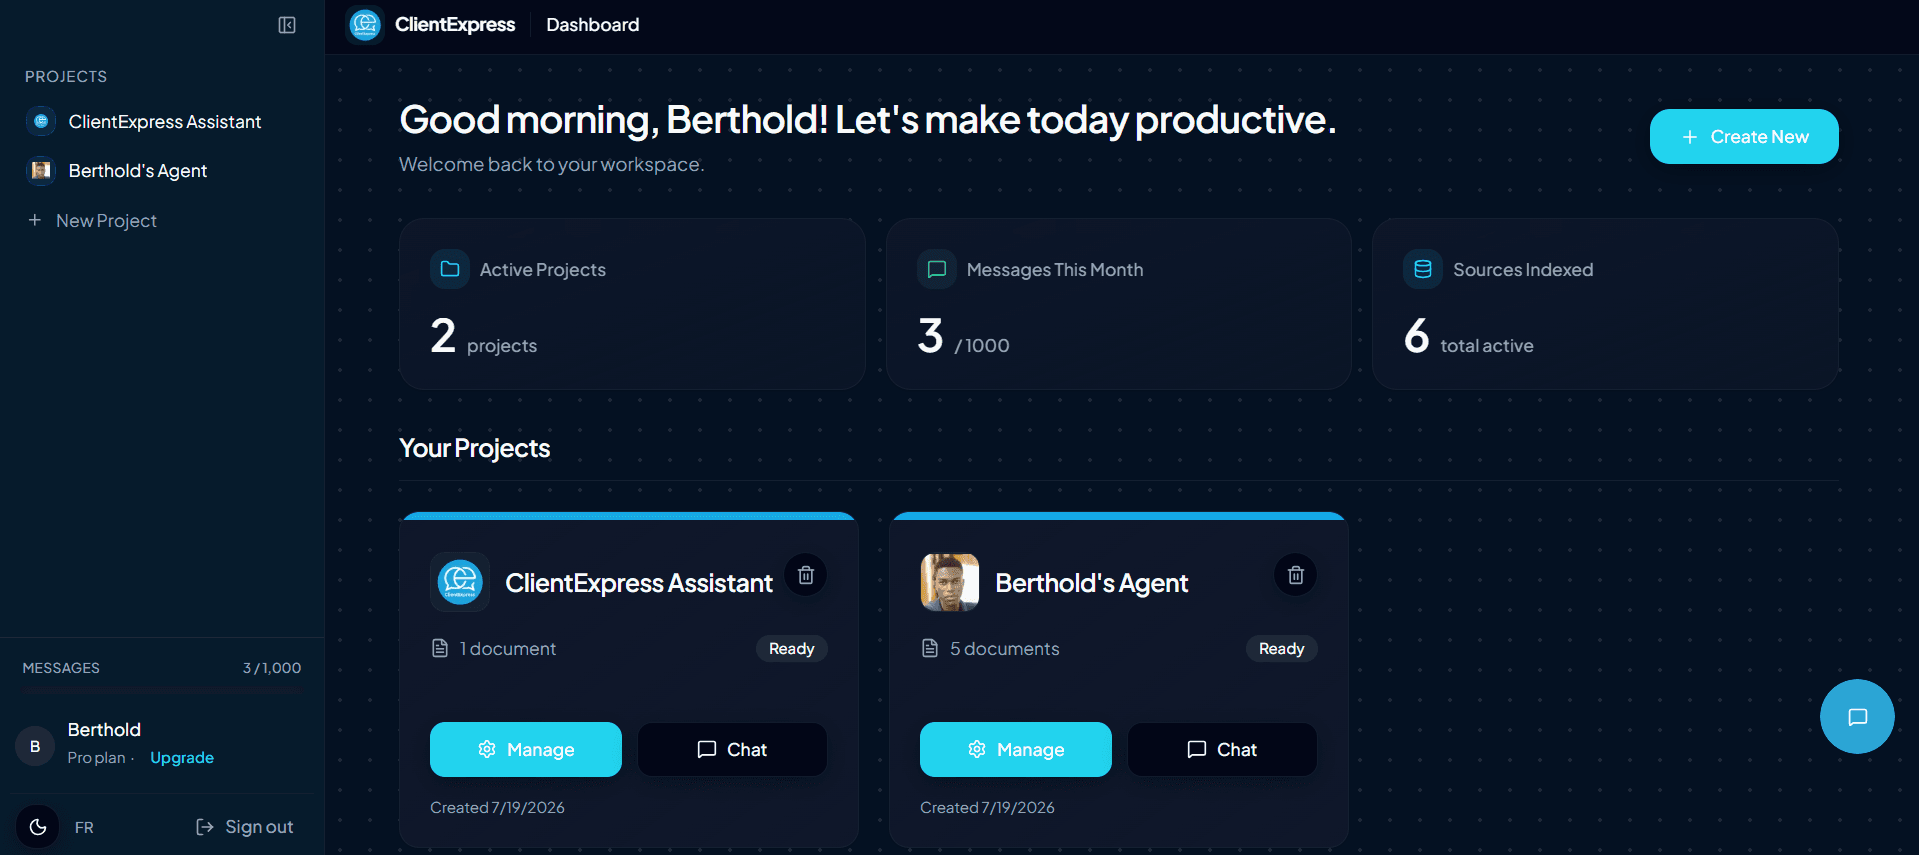
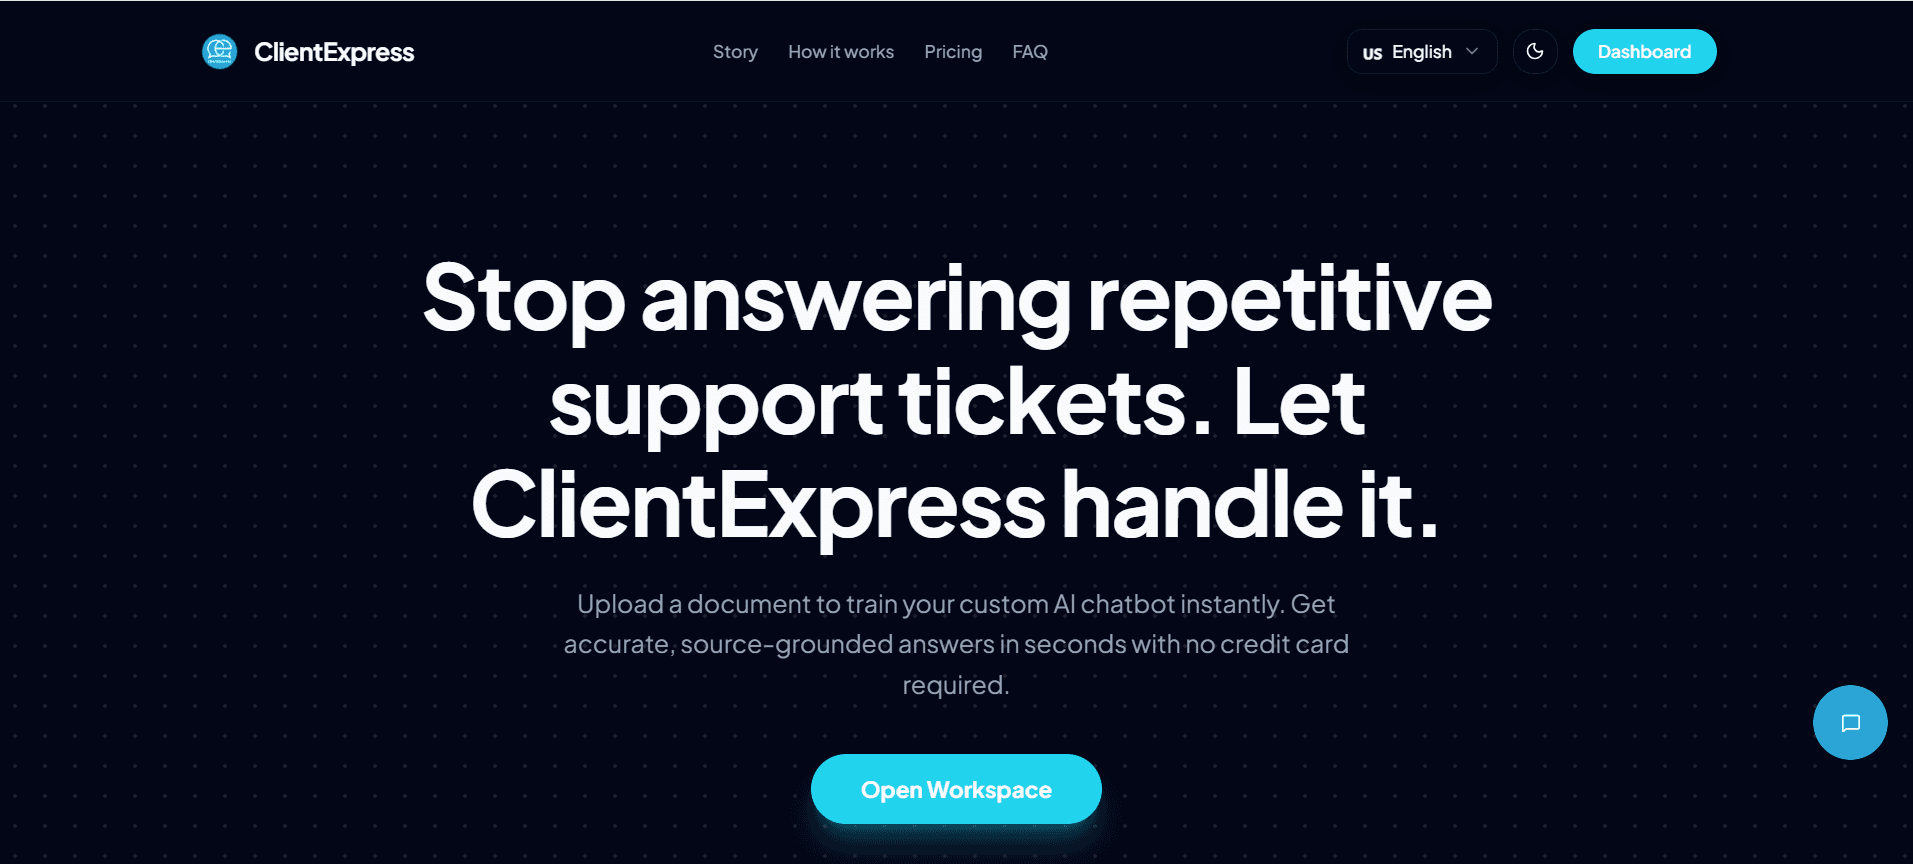
Client Express is a SaaS platform that turns a business's own documents into an AI customer-support chatbot it can embed on any website. Owners upload PDFs, Word files or URLs, and the bot answers visitors only from that content, in text or voice, in English or French. It targets a market most chatbot tools ignore: French-speaking customers who pay by mobile money.
At a Glance
14
LLMs, switchable per bot
42
Vitest test files
EN/FR
UI, text and voice
1 tag
to embed the widget
- Role
- Solo full-stack developer: product design, frontend, backend, AI pipeline, Python microservices and deployment.
- Timeline
- January – October 2026 · ~100 commits
- Status
- Live in production
The Problem
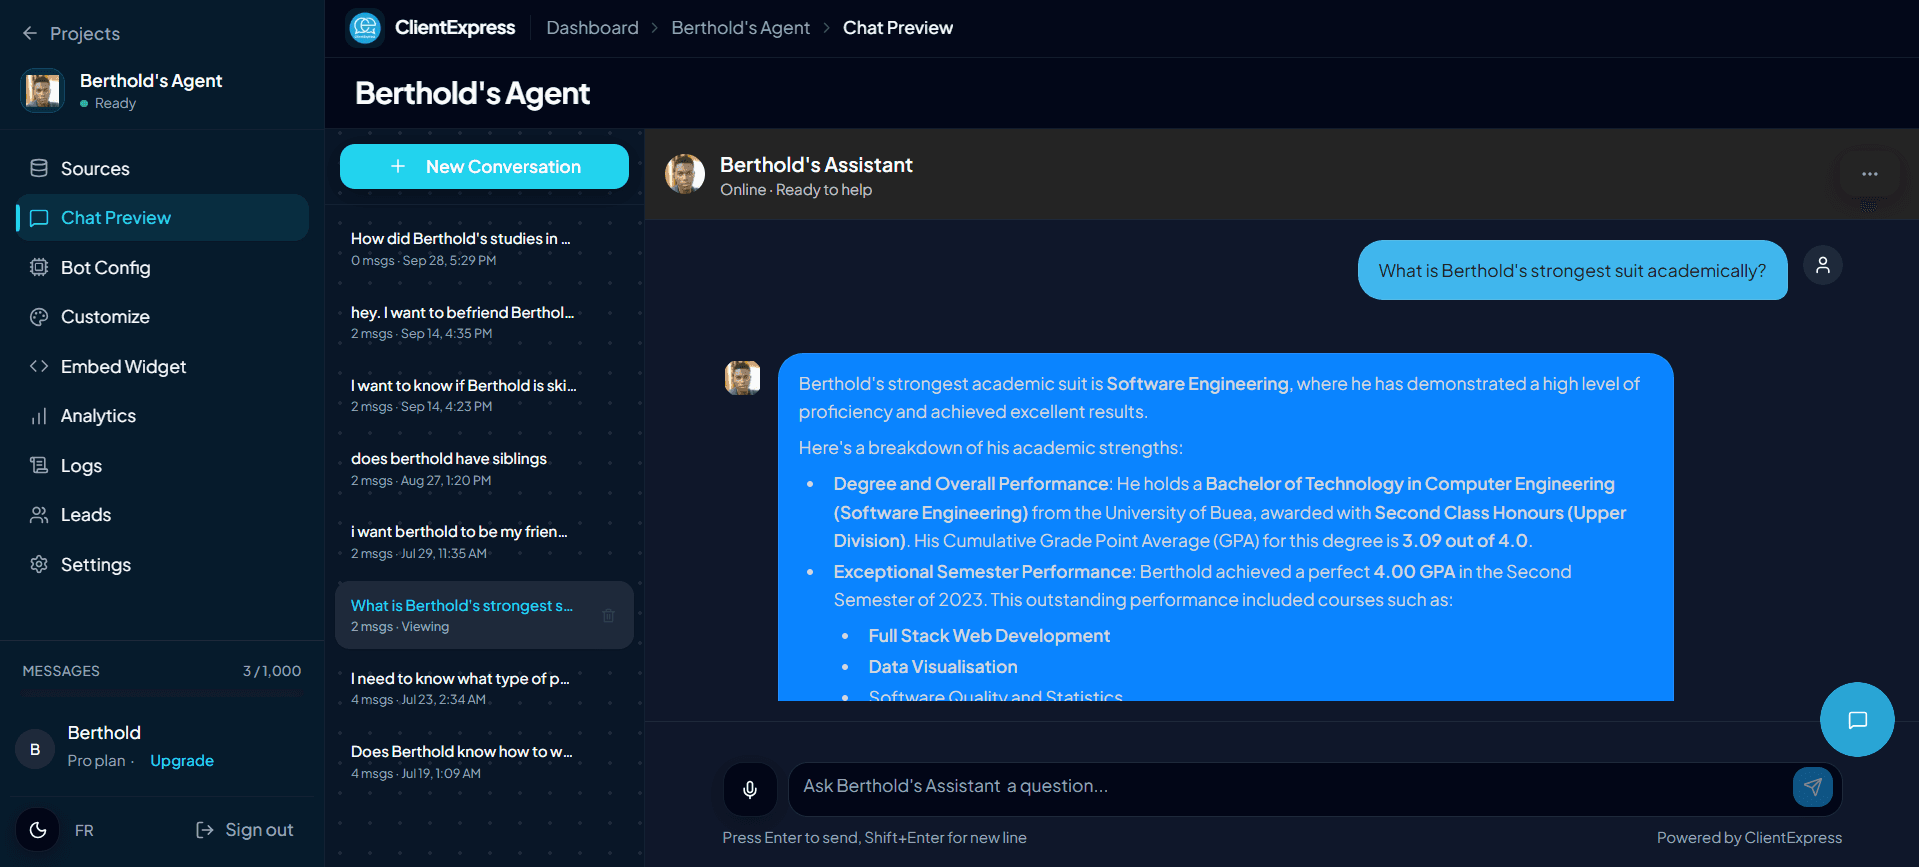
Small businesses answer the same customer questions every day, but generic AI chatbots invent answers they cannot back up. A wrong price or policy from a bot costs more trust than no bot at all. Client Express uses retrieval-augmented generation (RAG): the bot retrieves the relevant passages from the business's own documents and is instructed to answer only from them. When nothing relevant is found, it says so instead of guessing.
Technologies Used
App
Next.js 16, TypeScript, PostgreSQL
Dashboard, public REST API with OpenAPI 3.1 spec, billing
Retrieval
ChromaDB, hybrid semantic + keyword search
Reciprocal Rank Fusion, query rewriting, relevance thresholds
Models
Gemini, Mistral, Groq, OpenRouter
14 LLMs behind one model registry
Documents
Python microservices, Tesseract OCR, OpenCV
pypdf → pdfplumber → PyMuPDF fallback chain
Voice
Whisper, neural TTS
Speech-to-text and text-to-speech in the widget
Payments & hosting
CamPay, CinetPay, Docker, Railway, VPS
Mobile Money subscriptions with webhook confirmation
Key Features
- •Knowledge upload: PDF, DOCX, TXT, HTML, Markdown and URLs, with OCR for scanned PDFs and live training progress over SSE
- •Grounded answers that refuse to guess when no source passage is relevant
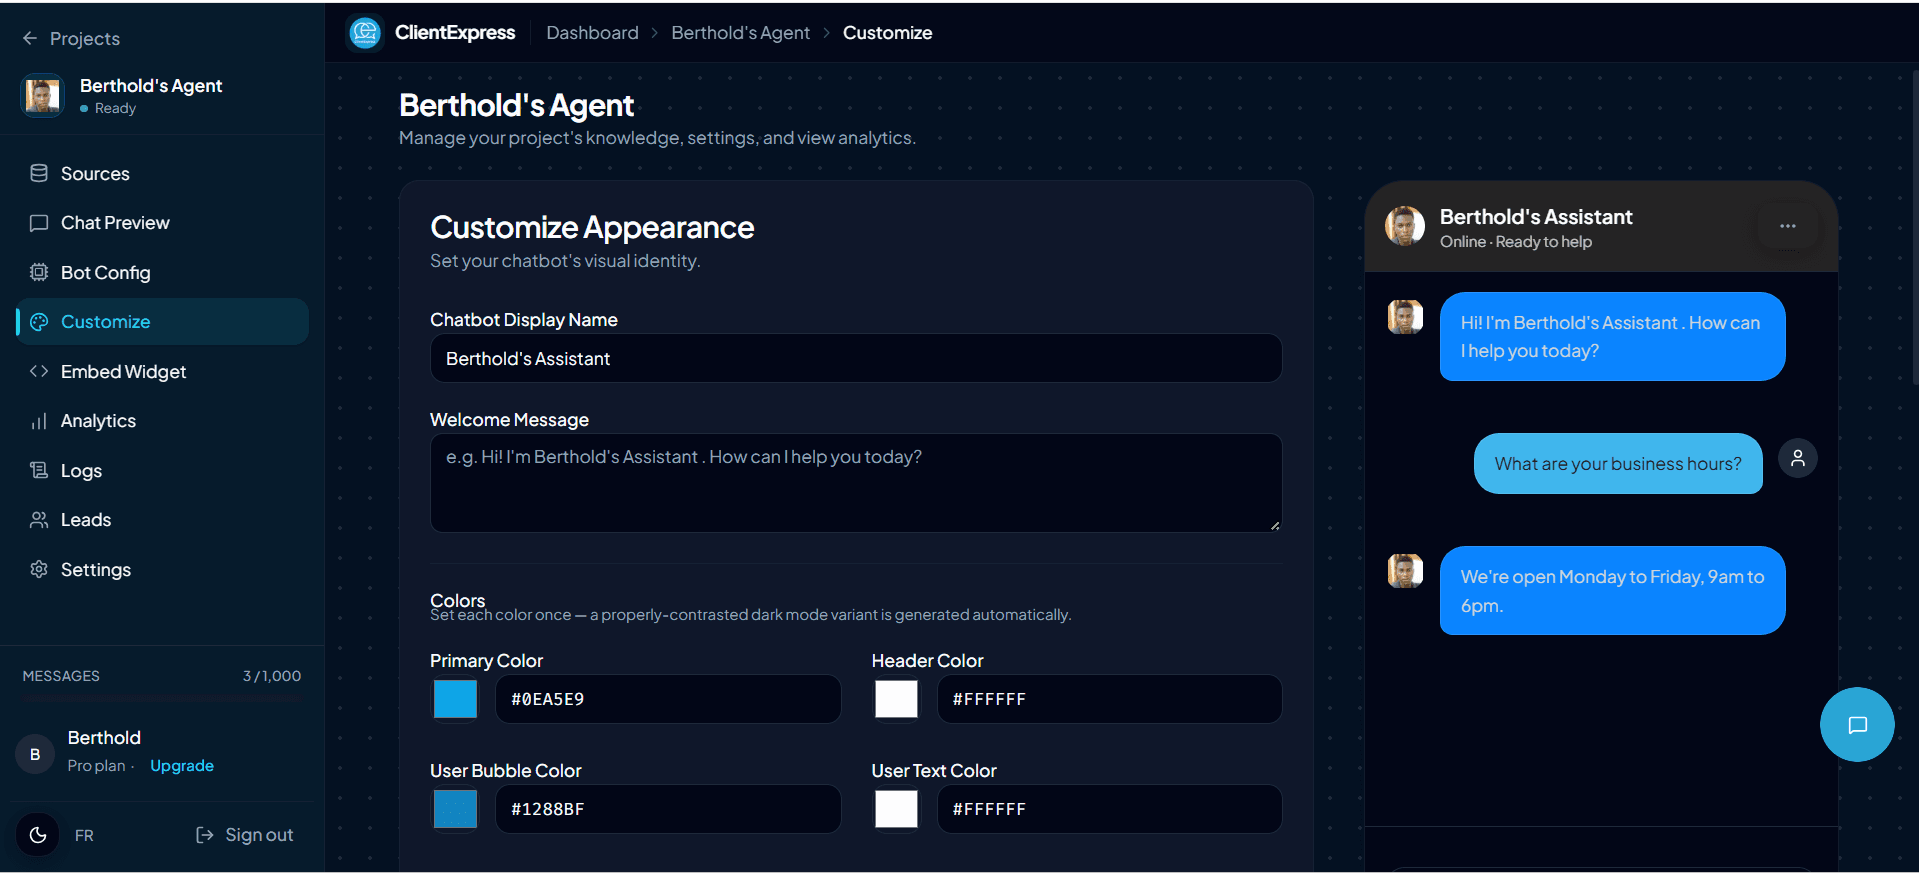
- •Embeddable widget: one script tag adds a branded chat bubble to any site
- •Real token-by-token streaming over server-sent events
- •Voice input and output with Whisper and neural voices
- •Lead capture inside the chat, once per session
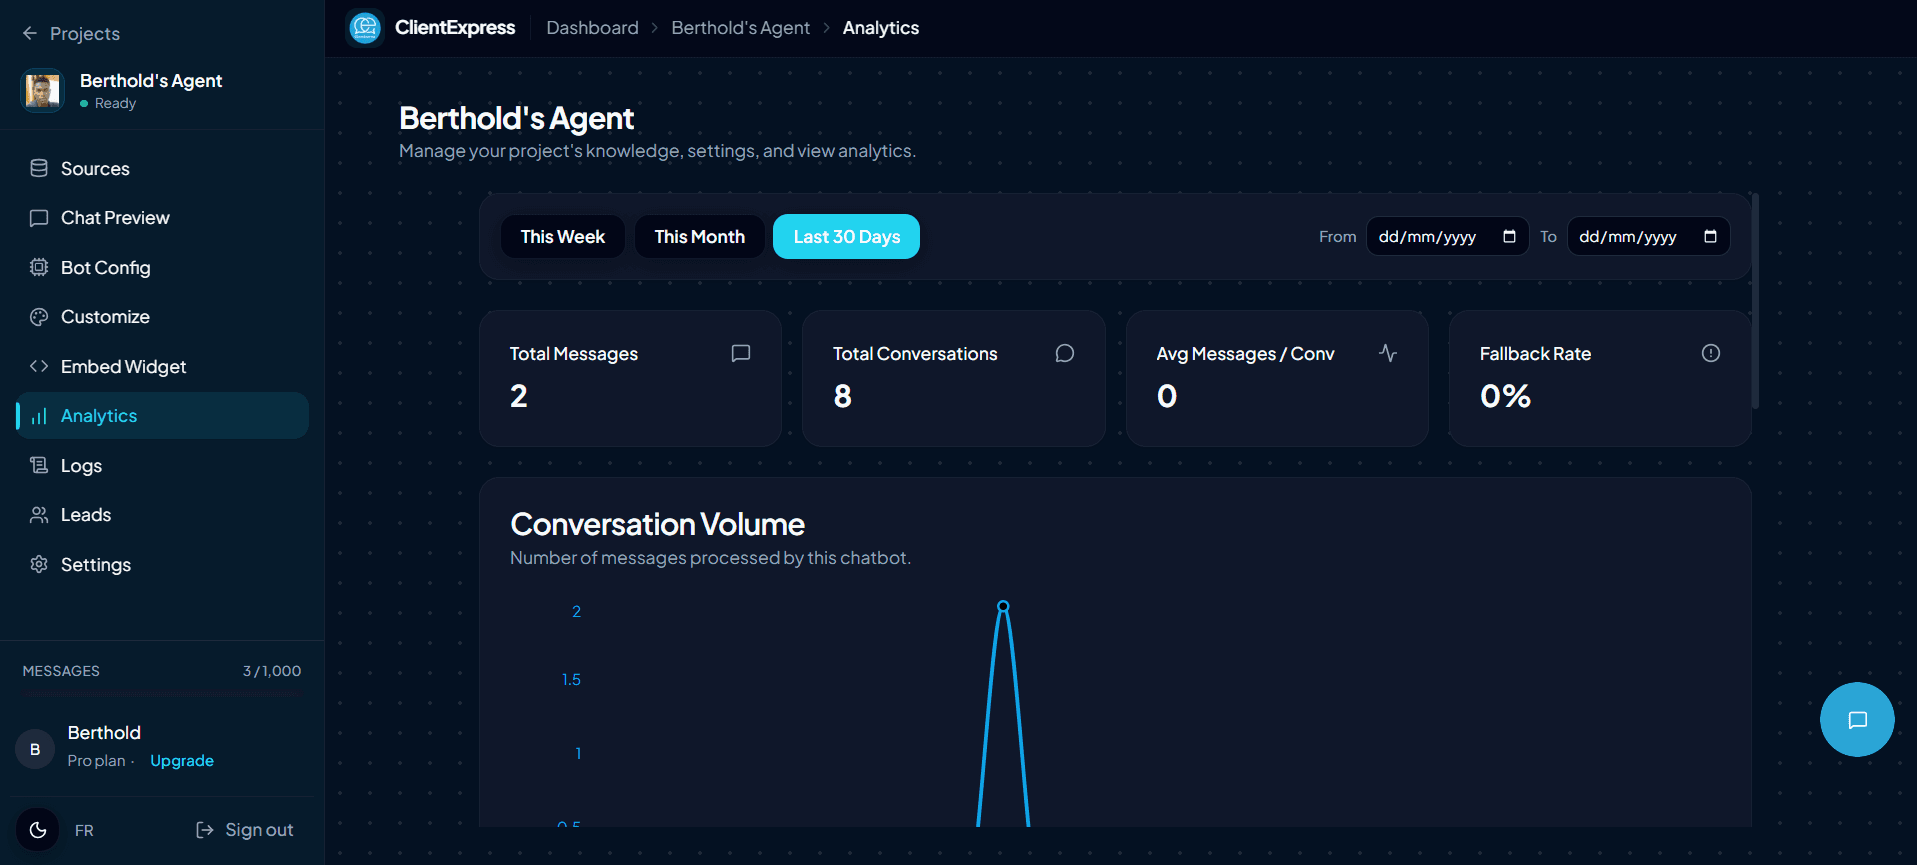
- •Analytics: conversation logs, usage stats and automatic topic grouping
- •Developer API with API keys and an interactive reference page
- •Custom domains verified through a DNS TXT record
- •Subscription plans paid by Mobile Money (CamPay, CinetPay)
Challenges & Solutions
01Retrieval that holds up in real conversations
Pure vector search missed exact terms like product codes, so I merged semantic and keyword results with Reciprocal Rank Fusion. An LLM step rewrites follow-ups such as "what about pricing?" into standalone queries before search. When no passage clears the relevance threshold, the bot points to the closest real document sections instead of guessing.
02Real token streaming
I replaced a simulated typewriter effect with true streaming over SSE. Answers were sometimes cut off silently, so I bypassed LangChain for Gemini to read the real finish reason and added end-of-stream markers on both sides. Incomplete answers now show a retry button.
03An embed bug only real customers saw
The widget worked on my own dashboard but broke on every customer site. Cross-origin testing with Playwright found the cause: the script took its base URL from the host page instead of its own script tag. The same pass fixed an infinite render loop and storage calls that browsers block in third-party iframes.
04Security hardening
I closed IDOR gaps where conversation routes lacked ownership checks, encrypted stored API keys with AES-256-GCM, added rate limiting and input sanitization, and fixed an auth redirect loop caused by sessions for deleted users.
05Robust document extraction
A Python service tries pypdf, then pdfplumber, then PyMuPDF. Scanned pages fall back to Tesseract OCR with automatic rotation correction and OpenCV preprocessing.
Outcome & Lessons
Client Express runs in production with Docker-packaged services, deployed on Railway and a Hostinger VPS. The product's own marketing site uses a Client Express chatbot for support.
- •Test the way customers use it: same-origin testing hid the widget bug for several rounds; only a true cross-origin setup exposed it.
- •RAG quality is mostly retrieval: exact-term misses and vague follow-ups were solved by hybrid search and query rewriting, not a bigger model.
- •Ownership checks belong on every route: an audit found IDOR gaps that normal use never triggered.
Project Gallery